Production Retrieval-Augmented Generation (RAG) demands far more than basic vector lookup and naive text splitting. In high-concurrency enterprise applications, retrieving the right context requires a nuanced combination of semantic embeddings, BM25 keyword matching, cross-encoder rerankers, and deterministic metadata filters. On this hub, you will find exhaustive architectural blueprints covering end-to-end RAG pipelines, chunking optimization benchmarks, multi-vector retrieval strategies, and memory store orchestration. Each guide breaks down real production tradeoffs between dense vector databases like Pinecone, Milvus, and pgvector versus Open Knowledge Format (OKF) files. Explore tested code snippets, latency budgets, and ingestion pipelines designed to minimize hallucinations while delivering sub-second query responses for mission-critical enterprise AI assistants.
5 In-Depth Guides-Last Updated: 2026-11-13
RECOMMENDED STARTING POINT
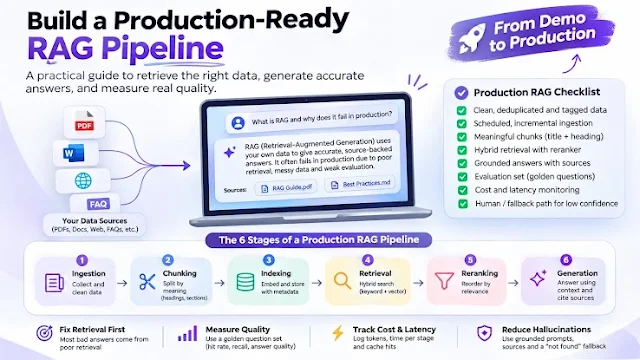
Production RAG Pipeline: The Architecture, Chunking and Evaluation Guide
Build a production RAG pipeline step by step: architecture, chunking, retrieval, evaluation and monitoring, with the mistakes to avoid before launch.
Most RAG demos work and most RAG products fail. Here is the full production architecture, the six stages that matter, how to measure quality, and the mistakes that quietly ruin answers.
AI applications need more than language models to deliver reliable answers. Learn how AI memory and RAG work together, how they differ, and how to build smarter apps using vector databases.
RAG lets an AI model answer from your own documents instead of guessing. Learn how retrieval-augmented generation works, when to use it, and how to build a simple version in Python.
Explore the architectural tradeoffs between traditional vector RAG and Open Knowledge Format (OKF) for enterprise AI, focusing on deterministic schema retrieval and hallucination prevention.