 AI Automation
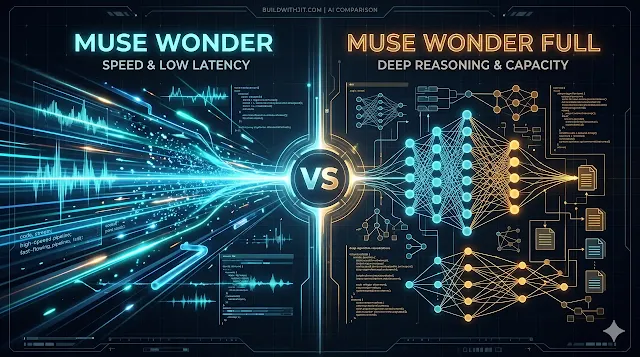
Muse Wonder vs. Muse Wonder Full: Deep Architecture Analysis, Benchmarks, and Production Routing Guide
Choosing between a low-latency model and a deep-reasoning powerhouse defines the unit economics of modern AI applications. This comprehensive technical breakdown compares Muse Wonder and Muse Wonder Full across inference speed, parameter density, multi-file debugging, and hybrid routing architectures.


